PostgreSQL
The PostgreSQL integration backs up PostgreSQL databases into a Kloset store and restores them. It supports logical dumps, logical dumps authenticated with an AWS IAM token, and physical base backups of the whole cluster.
The integration includes two connectors:
| Connector type | Description |
|---|---|
| Source connector | Back up PostgreSQL databases or a whole cluster into a Kloset store. |
| Destination connector | Restore a logical dump from a Kloset store to a running server (postgres, postgres+aws). |
The integration supports three protocols, each suited for different requirements:
| Protocol | Mechanism | Restore target |
|---|---|---|
postgres:// |
Logical dump via pg_dump / pg_dumpall |
A running PostgreSQL server |
postgres+aws:// |
Same as above, authenticated with an AWS IAM token | A running PostgreSQL server |
postgres+bin:// |
Physical base backup via pg_basebackup |
Any file-restore connector |
Requirements
- For
postgres://andpostgres+aws://, the PostgreSQL client tools in$PATHon the machine running Plakar, typically provided by thepostgresql-clientpackage:pg_dump,pg_dumpall: for backuppg_restore,psql: for restore and connectivity checks
- For
postgres+bin://,pg_basebackupin$PATH(samepostgresql-clientpackage, orpostgresqlon macOS via Homebrew). - For the directory dump format, Linux with
/dev/fuseandfusermount3(Debian packagefuse3). - Database-side requirements are listed under each protocol.
Typical use cases
- Scheduled logical backups of application databases with cross-version portability.
- RDS or Aurora backups authenticated through IAM without static credentials.
- Full-cluster physical snapshots for file-level disaster recovery.
- Selective database or schema restores from a full-cluster dump.
Installation
The PostgreSQL integration is distributed as a Plakar package.
Pre-compiled packages are available for common platforms and provide the simplest installation method.
Logging In
Pre-built packages require Plakar authentication. See Logging in to Plakar for details.
Install the PostgreSQL package:
$ plakar pkg add postgresqlVerify installation:
$ plakar pkg showSource builds are useful when pre-built packages are unavailable or when customization is required.
Prerequisites:
- Go toolchain compatible with your Plakar version
Build the package:
$ plakar pkg build postgresqlA package archive will be created in the current directory (e.g.,
postgresql_v1.0.0_darwin_arm64.ptar).
Install the package:
$ plakar pkg add -allow-unsigned ./postgresql_v1.0.0_darwin_arm64.ptarVerify installation:
$ plakar pkg showTo list, upgrade, or remove the package, see the managing packages guide.
Snapshot manifest
Every snapshot produced by this integration, with any protocol, contains a
/manifest.json record written before the backup data. It captures the cluster
state at the moment the backup was initiated and includes the following:
| Field | Description |
|---|---|
cluster_config |
Key server settings: data_directory, timezone, max_connections, wal_level, server_encoding, and others. |
roles |
All PostgreSQL roles with their attributes and group memberships. |
tablespaces |
All tablespaces with name, owner, filesystem location, and storage options. |
databases |
One entry per database: name, owner, encoding, collation, installed extensions, schemas, and a relations array. |
The relations array covers tables, partitioned tables, foreign tables, views,
materialized views, and sequences. Each entry includes schema, name, owner,
columns, constraints, indexes, partitioning metadata, row estimates, and
vacuum/analyze timestamps.
Metadata collection is best-effort. If a query fails, the affected field is omitted and the backup continues normally.
1. postgres protocol
The postgres protocol connects to a running PostgreSQL server and produces a
logical dump with pg_dump and pg_dumpall. A logical dump is a portable,
SQL-level representation of the data.
Every snapshot follows the same layout:
/00000-globals.sql: roles and tablespaces for the whole cluster (pg_dumpall --globals-only)./00001-<dbname>.dump,/00002-<dbname>.dump, …: onepg_dump -Fccustom-format file per database, numbered alphabetically. Withformat=directory, each database is a/00001-<dbname>/directory instead. See Dump formats.
When a single database is specified, only that database is dumped alongside
the globals file. When no database is specified, every database with
datallowconn = true is dumped, excluding template0. The snapshot also
contains the snapshot manifest.
Restore dispatches on file name and extension. .dump files are fed to
pg_restore, and 00000-globals.sql is fed to psql automatically.
Restore only trusted snapshots
A \! meta-command in 00000-globals.sql runs as a shell command on the
machine running plakar restore, even with exit_on_error. This applies to
both the postgres and postgres+aws protocols. To restore a snapshot you do
not trust, such as a .ptar received from someone else or a snapshot from an
unencrypted store others can write to, set no_globals=true and create the
roles and tablespaces on the target yourself.
Pros
- Portable across PostgreSQL major versions. You can dump on PG 15, restore on PG 16.
- Selectively back up individual databases or the whole cluster.
- Supports selective table or schema restore with
pg_restore -t. - No server downtime required.
Cons
- Requires a live, accessible PostgreSQL server for both backup and restore.
- Does not capture low-level objects (e.g. unlogged table contents, certain system catalog details).
- Restore time scales with data volume.
The backup user should be a superuser so that pg_dumpall can include role
passwords from pg_authid. On managed services such as Amazon RDS, the
administrative user is a restricted superuser and the integration cannot read
role passwords from pg_authid. In that case it automatically passes
--no-role-passwords to pg_dumpall and logs a warning. The dump is otherwise
complete, but restored roles have no password set.
A backup of all databases connects to the postgres database to list them, so
the backup user needs CONNECT on it. Some managed services, such as Clever
Cloud, do not grant it. Back up a single database there.
Database names that start with a dash, or contain = or whitespace, are refused
and the backup or restore fails. To back up the rest of a cluster that contains
one, list it in exclude_databases.
Backup flow
flowchart LR
subgraph Source["PostgreSQL Server"]
  DB["Databases"]
end

subgraph Plakar["Plakar"]
  Connector["pg_dump / pg_dumpall"]
  Transform["Encrypt & deduplicate"]

  Connector --> Transform
end

Store["Kloset Store"]

DB --> Connector
Transform --> Store
Restore flow
flowchart LR
Store["Kloset Store"]

subgraph Plakar["Plakar"]
  Transform["Decrypt & reconstruct"]
  Connector["pg_restore / psql"]

  Transform --> Connector
end

subgraph Destination["PostgreSQL Server"]
  DB["Databases"]
end

Store --> Transform
Connector --> DB
Dump formats
The format option selects how each database is dumped. Both formats apply to
the postgres and postgres+aws protocols.
The default, custom, dumps each database with a single pg_dump -Fc process
into one .dump file.
format=directory dumps each database with pg_dump -Fd, which writes one file
per table and dumps several tables in parallel. On large databases this shortens
backups considerably. Each file is streamed into the snapshot as it is written,
so the dump uses no local disk. parallel_dumps sets the number of parallel
jobs per database. Each job is a separate connection running a COPY on the
server. It defaults to 4, or to Plakar’s concurrency when that is lower. A
single table is always dumped by one job, so the largest table bounds how fast a
database can be dumped.
The directory format needs Linux with /dev/fuse and fusermount3. The backup
fails at startup when they are missing, or on any other platform. When Plakar
runs in a container, the container needs access to /dev/fuse, the SYS_ADMIN
capability, and an AppArmor profile that allows mounts.
Version requirement
With Plakar v1.1.8 and earlier, a format=directory backup can hang. Pass
-cache no to plakar backup to avoid it:
$ plakar at /var/backups backup -cache no "@mypg"To restore a directory-format snapshot, restore it to a local directory, or
mount it with plakar mount, and run
pg_restore -Fd on the database directory, such as 00001-myapp. When the
roles do not exist on the target, apply 00000-globals.sql with psql first.
Excluding tables
exclude_tables and exclude_table_data leave large tables out of a logical
backup. Both take a comma-separated list of pg_dump table patterns and apply
them to every database dumped:
exclude_tablesleaves out the table entirely, definition and rows (pg_dump --exclude-table).exclude_table_datakeeps the definition and leaves out the rows, so the table is restored empty (pg_dump --exclude-table-data).
A pattern without a schema only matches tables on the search_path. Use
*.audit_log to match a table in every schema. Excluding a partitioned table
does not exclude its partitions, which must be listed too. Both lists are
recorded in the snapshot manifest.
Shared configuration
The following options apply to both source and destination connectors using the
postgres protocol.
| Option | Required | Description |
|---|---|---|
location |
Yes | Connection URI: postgres://[user[:password]@]host[:port][/database] |
host |
No | Server hostname. Overrides the URI host. Defaults to localhost. |
port |
No | Server port. Overrides the URI port. Defaults to 5432. |
username |
No | PostgreSQL username. Overrides the URI user. |
password |
No | PostgreSQL password. Overrides the URI password. |
pg_bin_dir |
No | Directory containing the PostgreSQL client binaries. When omitted, binaries are resolved via $PATH. Useful when multiple PostgreSQL versions are installed. |
ssl_mode |
No | SSL mode: disable, allow, prefer, require, verify-ca, or verify-full. Defaults to prefer. |
ssl_cert |
No | Path to the client SSL certificate file (PEM). |
ssl_cert_data |
No | Inline PEM content of the client SSL certificate. Alternative to ssl_cert. |
ssl_key |
No | Path to the client SSL private key file (PEM). |
ssl_key_data |
No | Inline PEM content of the client SSL private key. Alternative to ssl_key. |
ssl_root_cert |
No | Path to the root CA certificate used to verify the server (PEM). |
ssl_root_cert_data |
No | Inline PEM content of the root CA certificate. Alternative to ssl_root_cert. |
Source configuration
The following extra options are available to source connectors using the
postgres protocol.
| Option | Required | Description |
|---|---|---|
database |
No | Database to back up. If omitted, all connectable databases are backed up. Overrides the URI path. |
exclude_databases |
No | Comma-separated list of database names to skip during a full backup. Has no effect when a single database is selected. |
exclude_tables |
No | Comma-separated pg_dump --exclude-table patterns. Matching tables are left out, definition and rows. See Excluding tables. |
exclude_table_data |
No | Comma-separated pg_dump --exclude-table-data patterns. Matching tables are restored empty. See Excluding tables. |
format |
No | Dump format: custom or directory. Defaults to custom. See Dump formats. |
parallel_dumps |
No | Number of parallel pg_dump jobs per database. Requires format=directory. Defaults to 4, or to Plakar’s concurrency when lower. |
compress |
No | Enable pg_dump compression. Defaults to false, so Plakar’s own compression and deduplication can operate on uncompressed data. See Limitations and scope. |
schema_only |
No | Dump only the schema (no data). Mutually exclusive with data_only. Defaults to false. |
data_only |
No | Dump only the data (no schema). Mutually exclusive with schema_only. Defaults to false. |
Destination configuration
The following extra options are available to destination connectors using the
postgres protocol.
| Option | Required | Description |
|---|---|---|
database |
No | Target database for pg_restore. If omitted, the name is inferred from the dump filename. Not used with recreate. |
databases |
No | Comma-separated list of database names to restore from a full backup. Only matching .dump files are restored. Globals are always included unless no_globals=true. |
clean |
No | Drop objects within the target database before recreating them (--clean --if-exists). The database must already exist. Mutually exclusive with recreate. Defaults to false. |
recreate |
No | Drop and recreate the target database from the archive metadata (-C --clean --if-exists). The postgres database is never dropped. Mutually exclusive with clean. Defaults to false. |
no_globals |
No | Skip restoring 00000-globals.sql. Set to true when the target server already has the required roles and tablespaces, or when the snapshot is not trusted. Defaults to false. |
no_owner |
No | Skip ALTER OWNER statements (--no-owner). Useful when roles from the source server do not exist on the target. Defaults to false. |
schema_only |
No | Restore only the schema (no data). Mutually exclusive with data_only. Defaults to false. |
data_only |
No | Restore only the data (no schema). Mutually exclusive with schema_only. Defaults to false. |
exit_on_error |
No | Stop on the first restore error. Applies to both pg_restore (-e) and psql (ON_ERROR_STOP=1). Defaults to false. |
Example
Back up a single database, or all databases including roles and tablespaces:
# Back up a single database
$ plakar source add mypg postgres://postgres:secret@db.example.com/myapp
$ plakar at /var/backups backup "@mypg"

# Back up all databases (roles, tablespaces, and data)
$ plakar source add mypg postgres://postgres:secret@db.example.com/
$ plakar at /var/backups backup "@mypg"

# Dump each database with 8 parallel jobs, keeping audit_log empty
$ plakar source add mypg postgres://postgres:secret@db.example.com/myapp \
  format=directory parallel_dumps=8 exclude_table_data=public.audit_log
$ plakar at /var/backups backup "@mypg"
Restore with different destination settings:
# Restore into an existing database (database must already exist)
$ plakar destination add mypgdst postgres://postgres:secret@db.example.com/myapp
$ plakar at /var/backups restore -to "@mypgdst" <snapshot_id>

# Drop objects first, then restore (database must exist)
$ plakar destination add mypgdst postgres://postgres:secret@db.example.com/myapp \
  clean=true
$ plakar at /var/backups restore -to "@mypgdst" <snapshot_id>

# Drop and recreate the database entirely (safe for fresh or existing clusters)
$ plakar destination add mypgdst postgres://postgres:secret@db.example.com/ \
  recreate=true
$ plakar at /var/backups restore -to "@mypgdst" <snapshot_id>

# Restore a single database from a full backup
$ plakar destination add mypgdst postgres://postgres:secret@db.example.com/ \
  databases=myapp recreate=true
$ plakar at /var/backups restore -to "@mypgdst" <snapshot_id>

# Restore, skipping owner assignment (useful when roles differ on the target)
$ plakar destination add mypgdst postgres://postgres:secret@db.example.com/myapp \
  no_owner=true
$ plakar at /var/backups restore -to "@mypgdst" <snapshot_id>
2. postgres+aws protocol
The postgres+aws protocol performs the same logical backup as postgres, but
authenticates with a short-lived IAM token rather than a static password. The
token is generated automatically through the AWS SDK before pg_dump or
pg_dumpall runs. The SDK uses its standard credential chain: environment
variables, ~/.aws/credentials, EC2/ECS instance metadata, and so on. No
password parameter is needed or accepted.
The backup output is identical to postgres:// and can be restored with the
same postgres:// destination connector. The backup and restore flows are the
same as for the postgres protocol.
AWS setup
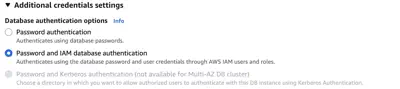
Enable IAM authentication on the RDS instance
Enable IAM database authentication on the RDS instance through the AWS console, CLI, or Terraform. It can be set at creation time or toggled on an existing instance.
Create an IAM policy with rds-db:connect
Attach the following policy to the IAM user or role that runs Plakar. See Managing IAM Roles, Users, and Access Keys for instructions on creating policies and attaching them to a user or role.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": "rds-db:connect",
      "Resource": "arn:aws:rds-db:REGION:ACCOUNT_ID:dbuser:DB_RESOURCE_ID/DB_USER"
    }
  ]
}REGION: e.g.eu-west-3ACCOUNT_ID: your 12-digit AWS account IDDB_RESOURCE_ID: the RDS instance resource ID (e.g.db-ABCDEFGHIJKL1234), found in the RDS console under ConfigurationDB_USER: the PostgreSQL username Plakar connects as
Create the PostgreSQL user with IAM login
Connect to the database as a superuser and run:
CREATE USER myuser WITH LOGIN;
GRANT rds_iam TO myuser;
The user must not have a password set. Authentication is handled entirely by the IAM token.
Providing credentials
Suitable for local testing:
export AWS_ACCESS_KEY_ID=AKIAIOSFODNN7EXAMPLE
export AWS_SECRET_ACCESS_KEY=wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY
export AWS_REGION=eu-west-3

$ plakar source add myrds \
  postgres+aws://myuser@mydb.cluster-xyz.eu-west-3.rds.amazonaws.com/myapp \
  region=eu-west-3 ssl_mode=require
$ plakar at /var/backups backup "@myrds"
If the IAM user requires a session token (assumed role, temporary credentials):
export AWS_SESSION_TOKEN=AQoDYXdzEJr...Suitable for local testing with a shared credentials file:
# ~/.aws/credentials
[default]
aws_access_key_id     = AKIAIOSFODNN7EXAMPLE
aws_secret_access_key = wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY# ~/.aws/config
[default]
region = eu-west-3The SDK picks up the profile automatically. To use a named profile:
export AWS_PROFILE=myprofile
$ plakar at /var/backups backup "@myrds"
The recommended approach for production. Attach an IAM role with the
rds-db:connect policy to the EC2 instance running Plakar. No credentials need
to be configured. The SDK retrieves short-lived credentials from the instance
metadata service automatically.
$ plakar source add myrds \
  postgres+aws://myuser@mydb.cluster-xyz.eu-west-3.rds.amazonaws.com/myapp \
  region=eu-west-3 ssl_mode=require
$ plakar at /var/backups backup "@myrds"
Shared configuration
The following options apply to both source and destination connectors using the
postgres+aws protocol.
| Option | Required | Description |
|---|---|---|
location |
Yes | Connection URI: postgres+aws://[user@]host[:port][/database]. No password component. The IAM token is fetched automatically. |
host |
No | RDS instance hostname. Overrides the URI host. Defaults to localhost. |
port |
No | RDS instance port. Overrides the URI port. Defaults to 5432. |
username |
No | PostgreSQL username. Must be an IAM-enabled database user. Overrides the URI user. |
region |
Yes | AWS region of the RDS instance, e.g. us-east-1. |
pg_bin_dir |
No | Directory containing the PostgreSQL client binaries. When omitted, binaries are resolved via $PATH. |
ssl_mode |
No | SSL mode. Defaults to prefer. IAM authentication requires an encrypted connection. Use require or higher. |
ssl_cert |
No | Path to the client SSL certificate file (PEM). |
ssl_cert_data |
No | Inline PEM content of the client SSL certificate. Alternative to ssl_cert. |
ssl_key |
No | Path to the client SSL private key file (PEM). |
ssl_key_data |
No | Inline PEM content of the client SSL private key. Alternative to ssl_key. |
ssl_root_cert |
No | Path to the root CA certificate used to verify the server (PEM). |
ssl_root_cert_data |
No | Inline PEM content of the root CA certificate. Alternative to ssl_root_cert. |
Source configuration
The following extra options are available to source connectors using the
postgres+aws protocol.
| Option | Required | Description |
|---|---|---|
database |
No | Database to back up. If omitted, all connectable databases are backed up. Overrides the URI path. |
exclude_databases |
No | Comma-separated list of database names to skip. Defaults to rdsadmin (an internal AWS system database). Set to an empty string to disable all exclusions. |
exclude_tables |
No | Comma-separated pg_dump --exclude-table patterns. Matching tables are left out, definition and rows. See Excluding tables. |
exclude_table_data |
No | Comma-separated pg_dump --exclude-table-data patterns. Matching tables are restored empty. See Excluding tables. |
format |
No | Dump format: custom or directory. Defaults to custom. See Dump formats. |
parallel_dumps |
No | Number of parallel pg_dump jobs per database. Requires format=directory. Defaults to 4, or to Plakar’s concurrency when lower. |
compress |
No | Enable pg_dump compression. Defaults to false, so Plakar’s own compression and deduplication can operate on uncompressed data. |
schema_only |
No | Dump only the schema (no data). Mutually exclusive with data_only. Defaults to false. |
data_only |
No | Dump only the data (no schema). Mutually exclusive with schema_only. Defaults to false. |
Destination configuration
The postgres+aws destination connector supports the same options as the
postgres destination connector, minus
password, plus region. An IAM token is generated automatically and used as
the connection password.
Example
Back up a single RDS database, or all databases on an RDS instance:
# Back up a single RDS database
$ plakar source add myrds \
  postgres+aws://myuser@mydb.cluster-xyz.us-east-1.rds.amazonaws.com/myapp \
  region=us-east-1 ssl_mode=require
$ plakar at /var/backups backup "@myrds"

# Back up all databases on an RDS instance
$ plakar source add myrds \
  postgres+aws://myuser@mydb.cluster-xyz.us-east-1.rds.amazonaws.com/ \
  region=us-east-1 ssl_mode=require
$ plakar at /var/backups backup "@myrds"
Restore to RDS:
# Restore into an existing database on RDS
$ plakar destination add myrds \
  postgres+aws://myuser@mydb.cluster-xyz.us-east-1.rds.amazonaws.com/myapp \
  region=us-east-1 ssl_mode=require
$ plakar at /var/backups restore -to "@myrds" <snapshot_id>

# Drop and recreate the database entirely
$ plakar destination add myrds \
  postgres+aws://myuser@mydb.cluster-xyz.us-east-1.rds.amazonaws.com/ \
  region=us-east-1 ssl_mode=require recreate=true
$ plakar at /var/backups restore -to "@myrds" <snapshot_id>

# Restore, skipping owner assignment
$ plakar destination add myrds \
  postgres+aws://myuser@mydb.cluster-xyz.us-east-1.rds.amazonaws.com/myapp \
  region=us-east-1 ssl_mode=require no_owner=true
$ plakar at /var/backups restore -to "@myrds" <snapshot_id>
3. postgres+bin protocol
The postgres+bin protocol runs pg_basebackup to stream a tar archive of the
entire PostgreSQL data directory (PGDATA) directly from the server’s
replication interface. Each file inside the tar is stored as an individual
record in the snapshot, preserving paths, permissions, and timestamps.
Because the backup operates at the file level, it captures the entire
cluster: all databases, configuration files, and the WAL segments required for
a consistent recovery. No subpath can be specified, since pg_basebackup always
backs up the whole cluster. The snapshot also contains the
snapshot manifest.
Pros
- Fast backup and restore regardless of data volume, because it is a file copy, not a query.
- Captures everything in a single operation: all databases, configuration, global objects, and WAL.
- The restored cluster can be started directly with any PostgreSQL binary of the same major version. No running server is needed at restore time.
Cons
- Version-locked. The backup must be restored with the same PostgreSQL major version.
- Cannot selectively restore a single database or table.
- Requires a replication-capable user (or superuser) and
wal_level >= replicaon the server. - The PostgreSQL server must be stopped before the data directory is replaced with the restored files.
The PostgreSQL server must have:
wal_level = replica(or higher) inpostgresql.conf- A user with the
REPLICATIONprivilege (or a superuser) pg_hba.confallowing a replication connection from the backup host
Backup flow
flowchart LR
subgraph Source["PostgreSQL Server"]
  PGDATA["PGDATA (all databases)"]
end

subgraph Plakar["Plakar"]
  Connector["pg_basebackup
 (replication stream)"]
  Transform["Encrypt & deduplicate"]

  Connector --> Transform
end

Store["Kloset Store"]

PGDATA --> Connector
Transform --> Store
Source configuration
The postgres+bin protocol has a source connector only.
| Option | Required | Description |
|---|---|---|
location |
Yes | Connection URI: postgres+bin://[user[:password]@]host[:port]. A subpath is not supported. |
host |
No | Server hostname. Overrides the URI host. Defaults to localhost. |
port |
No | Server port. Overrides the URI port. Defaults to 5432. |
username |
No | PostgreSQL replication username. Overrides the URI user. |
password |
No | PostgreSQL password. Overrides the URI password. |
pg_bin_dir |
No | Directory containing pg_basebackup. When omitted, resolved via $PATH. |
ssl_mode |
No | SSL mode: disable, allow, prefer, require, verify-ca, or verify-full. Defaults to prefer. |
ssl_cert |
No | Path to the client SSL certificate file (PEM). |
ssl_cert_data |
No | Inline PEM content of the client SSL certificate. Alternative to ssl_cert. |
ssl_key |
No | Path to the client SSL private key file (PEM). |
ssl_key_data |
No | Inline PEM content of the client SSL private key. Alternative to ssl_key. |
ssl_root_cert |
No | Path to the root CA certificate used to verify the server (PEM). |
ssl_root_cert_data |
No | Inline PEM content of the root CA certificate. Alternative to ssl_root_cert. |
Example
# Back up the entire cluster
$ plakar source add mypg postgres+bin://replicator:secret@db.example.com
$ plakar at /var/backups backup "@mypg"
Restoring a physical backup
There is no dedicated destination connector for postgres+bin://. The snapshot
contains plain files, so any file-restore connector can write them back to disk.
The resulting directory is a valid PostgreSQL data directory that can be started
directly.
Stop the server before restoring
The data directory must not be in use by a running PostgreSQL instance before restoration begins. Stop the server first, or restore to a fresh directory as shown below.
# Restore the data directory locally
$ plakar at /var/backups restore -to ./pgdata <snapshot_id>

# Start PostgreSQL against the restored data directory
$ docker run --rm \
  -v "$PWD/pgdata:/var/lib/postgresql/data" \
  postgres:<postgres_version>

# Restore to a remote host via SFTP
$ plakar at /var/backups restore -to sftp://user@host/var/lib/postgresql/data <snapshot_id>
# then on the remote host:
$ pg_ctl -D /var/lib/postgresql/data start
Replace <postgres_version> with the same major version that was running
when the backup was taken (e.g. 17).
Limitations and scope
pg_dump compression is disabled by default. With compress=false, Plakar’s
own compression and deduplication operate on the raw data stream. A
pre-compressed dump is an incompressible stream, which reduces both compression
efficiency and cross-snapshot deduplication. Depending on network bandwidth and
store backend, enabling pg_dump compression may be more efficient for very
large databases. This trade-off warrants further benchmarking across different
workloads.